I will audit your AI model's answers in pharmacy and life sciences

Paras
Data annotation & AI training data
About this service
What Paras needs from you to start
To start the evaluation sprint, please provide: Project Objective & Task Type: (e.g., RLHF evaluation, CoT reasoning verification, adversarial red-teaming, or domain test-suite generation). Evaluation Guidelines & Rubrics: Your grading criteria, severity thresholds (critical, major, minor), attribution standards, and edge-case definitions. Input Data / Target Prompts: The raw prompts, model response pairs, or technical source files (CSV, JSONL, Google Sheets, or PDF). Specific Scientific/Technical Focus: Any particular domains required (e.g., pharmacokinetics, dissolution modeling, analytical spectra, chemical safety, or medical literature fact-checking). Output Format Preference: Your preferred delivery schema (structured JSON, annotated spreadsheet, or markdown report).
Compare packages
| Package | $70 Essential | $200 Standard | $450 Premium |
|---|---|---|---|
| Included |
|
|
|
| Delivery | 2 days | 4 days | 5 days |
| Revisions | 1 | 2 | 3 |
FAQ
Which file formats and evaluation environments do you accept? +
I accept datasets in CSV, JSON, JSONL, XLSX, Google Sheets, or PDF. I can also perform live evaluations directly inside your proprietary annotation interface, Label Studio, or custom evaluation portal if guest/evaluator access is provided.
What specific pharmaceutical and life sciences subfields do you cover? +
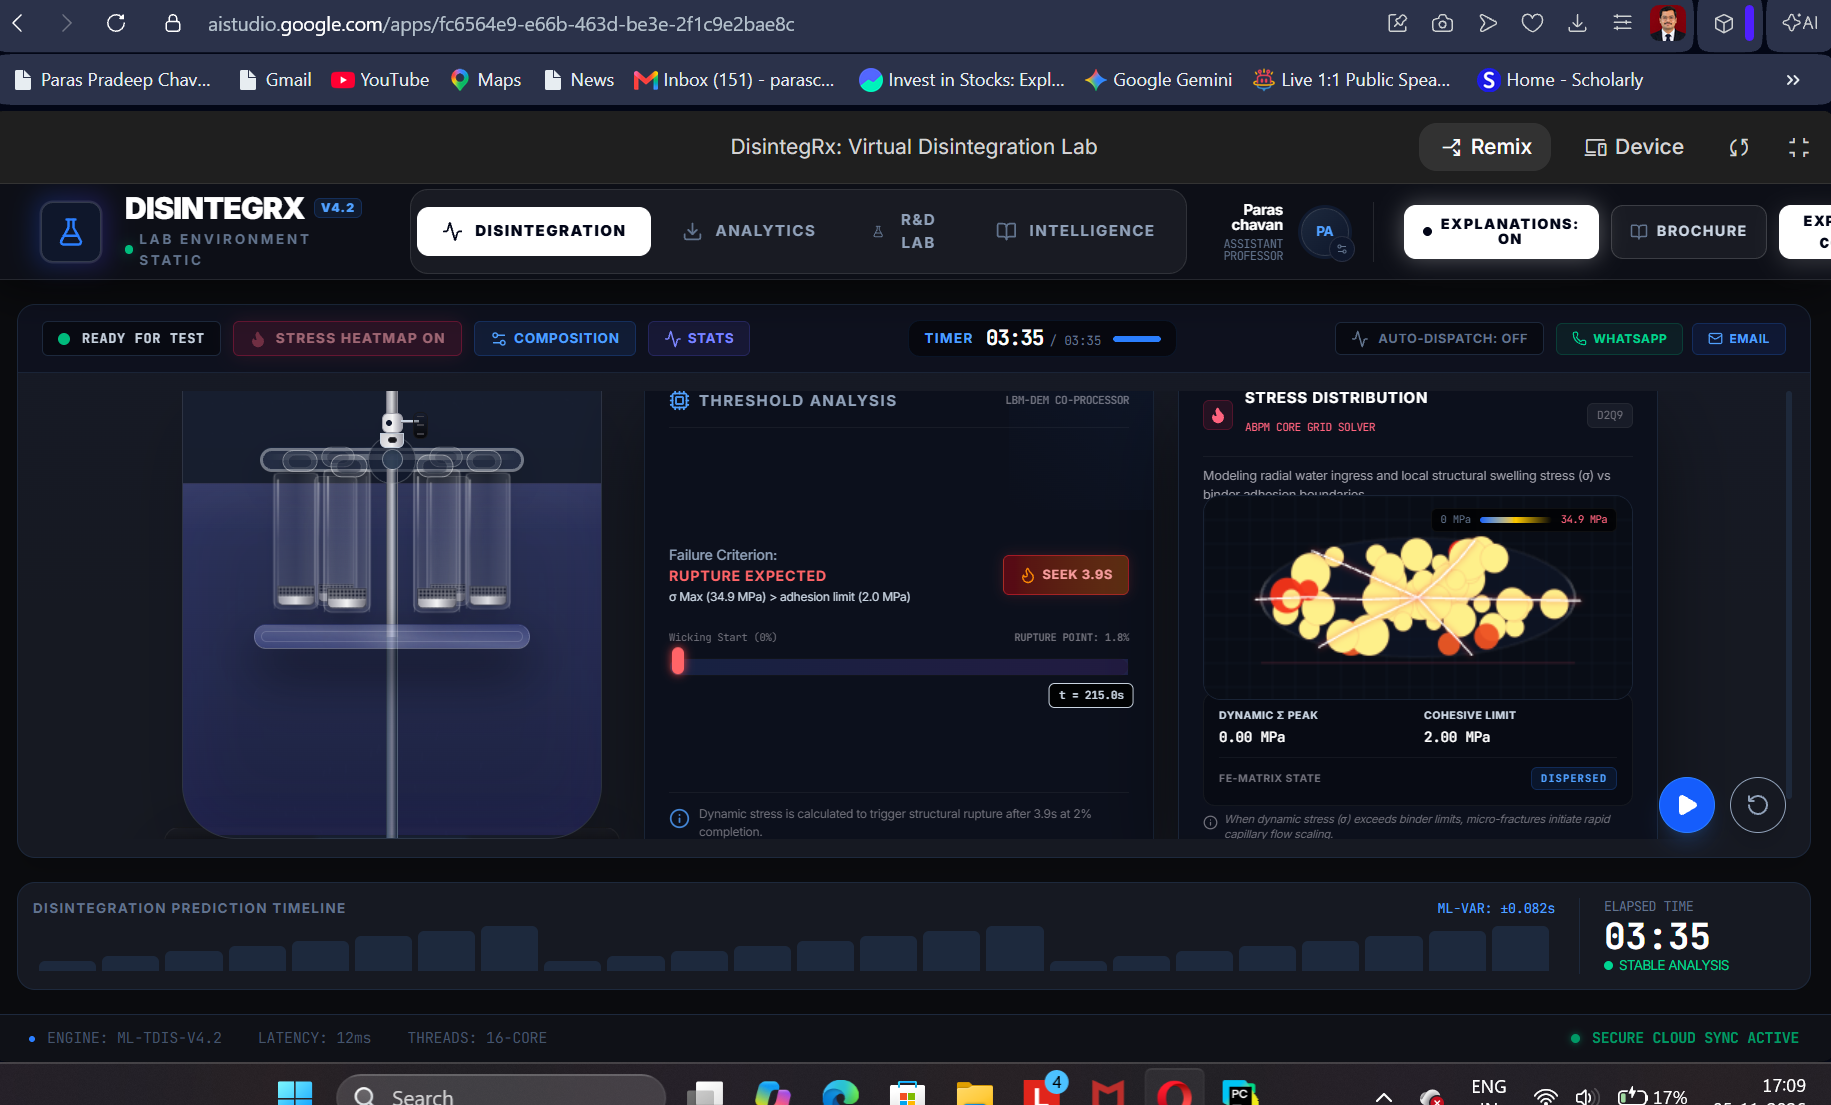
My core domain coverage includes novel drug delivery systems (NDDS, niosomes, liposomes), pharmacokinetics and release kinetics, analytical chemistry data (HPLC, UV-Vis spectra, dissolution profiles), in-silico toxicology (LD50, organ toxicity), and OTC/prescription regulatory standards.
How do you identify and categorize scientific hallucinations? +
I evaluate responses using multi-tier severity classifications: Critical: Factually hazardous medical claims, inverted therapeutic dosing, or invalid chemical safety profiles. Major: Mathematically broken release equations, kinetic boundary violations, or misattributed analytical peaks. Minor: Slight nomenclature discrepancies or formatting deviations that do not alter the underlying scientific validity.
Can you deliver step-by-step Chain-of-Thought (CoT) reasoning data? +
Yes. I formulate and audit explicit step-by-step derivation paths, mathematical formulas, and empirical literature citations to ensure every reasoning link can be evaluated independently by your fine-tuning pipeline.
About the seller

Paras ✓ Reviewed talent
View full profile →- Member since
- Nov 2026
- Services
- 1
M.Pharm academic, published researcher, and registered pharmacist specializing in life sciences AI evaluation, CoT reasoning verification, and adversarial red-teaming. I audit chemical safety, drug kinetics, and complex multimodal data against empirical lab benchmarks to eliminate technical hallucinations.
Reviews
No reviews yet
Reviews appear after completed orders. Only buyers who paid for this service on RemoteAI can leave one.
More Data annotation & AI training data services
Ankit
I will label your Audio, images, video, and text data accurately for AI training
From $100
Habiba
I will prepare clean annotate datasets to improve AI model training
From $75
Kirstie
I will label your images, text ,audio data accurately for AI training
From $100
Dhruv
I will annotate robotics videos and label AI training data accurately
From $100
From
$70